AI Platform & Agentic Systems Engineer · Independent Consultant

Mohsen Seyedkazemi Ardebili

I build autonomous AI that acts on infrastructure.

Not a chatbot that explains your cluster — systems that observe it, reason about failures, and execute remediation, with a human at the gate. LLM agents for Kubernetes & HPC, anomaly detection on Tier-0 supercomputers, and the MLOps to run it in production.

  • BASED Italy · remote across Europe & internationally
  • EXP 6 yrs 1,000 MW plant → PhD (engineering) · HPC thermal research
  • OSS KubeIntellect · AOBench · YazSes

Deep dives KubeIntellect NovaFabric AOBench IDKMesh

control_loop.svc live

telemetry in → root-cause reasoning → gated action → back to telemetry

// profile

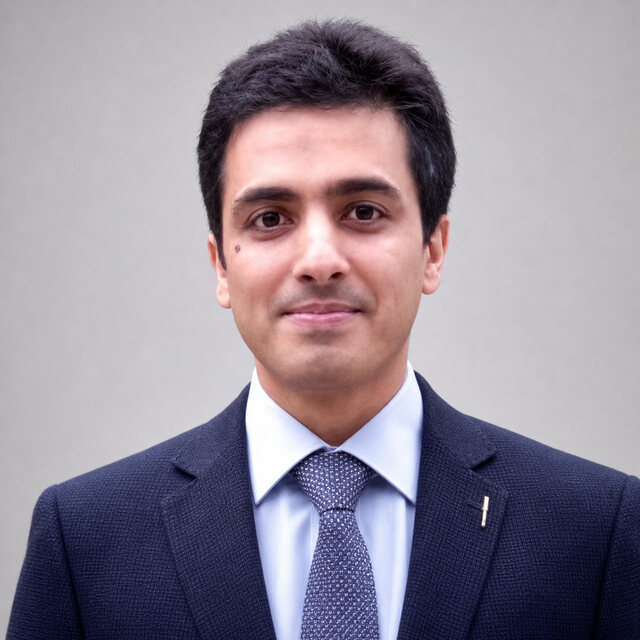
Portrait of Mohsen Seyedkazemi Ardebili
available for collaboration

From a power plant's networks to the control plane of a datacenter.

I spent nearly nine years in enterprise IT and network operations — six of them as the IT & Network Administrator of a 1,000+ MW combined-cycle power plant, running the network across eleven operational zones, where downtime is not an abstraction. Then I did a PhD at the University of Bologna on detecting and predicting thermal anomalies in a Tier-0 supercomputer.

That path gives me a lens most ML researchers don't have: I care about uptime, observability, and correctness in production — not just benchmark numbers. Today I design autonomous control for infrastructure: systems that detect failures, reason about root cause, and propose or execute remediation behind human-approval gates.

I was a Postdoctoral Research Fellow at DEI, University of Bologna from August 2022 to September 2026, working across EU Horizon and EuroHPC projects including DECICE and SEANERGYS. I now work as an independent consultant on AI platform and MLOps systems, alongside open-source systems I build and maintain.

// systems  —  research-grade work, in the open

AI SRE and AIOps systems for Kubernetes and HPC.

Things that act, with the receipts — KubeIntellect works on a live Kubernetes cluster and stops for a human before it changes anything; AOBench measures whether an agent stays inside its permissions, against reproducible HPC snapshots.

A modular, LLM-orchestrated multi-agent framework for end-to-end Kubernetes operations — root-cause analysis, diagnosis, and human-gated cluster actions across the full API surface (read, write, exec, delete, RBAC, lifecycle). A stateful LangGraph supervisor coordinates domain agents; in the published architecture a Code-Generator agent synthesised and validated new tools at runtime. Published in the Journal of Grid Computing (2026, 24(3):17).

  • Stateful LangGraph supervisor + PostgreSQL checkpoints
  • Human-in-the-loop approval on every mutating operation
  • Runtime tool synthesis with AST validation and a Kubernetes API whitelist (paper architecture)
  • Deployed on Azure AKS — OpenAI-compatible FastAPI backend
PythonLangGraphFastAPIKubernetesPostgreSQLAzure AKS

Agent Operations Benchmark — a trace-driven, role-aware, RBAC-enforced benchmark for LLM agents that operate HPC systems. It asks the blunt question: can an autonomous agent be trusted to run a supercomputer? — and scores the answer against real operator roles and hard policy constraints.

88 tasks29 environments16 systems
  • 88 tasks across 10 question categories × 5 operator roles (release v0.4.1)
  • 29 deterministic environment bundles — 23 synthetic, 6 built from real Marconi100 telemetry
  • Permission-enforced: a policy violation hard-fails the task, whatever the answer said
  • Scored on 7 weighted dimensions, rolled into a CLEAR scorecard (Cost · Latency · Efficacy · Assurance · Reliability)
  • 16 model systems evaluated on the 59-task dev split, every headline number tied to a frozen run ID
10 CAT × 5 ROLES POLICY HARD FAIL C · L · E · A · R 88 TASKS CLEAR SCORECARD
a policy breach hard-fails the task
PythonLLM EvalMCPSLURM

Verified swarm engineering — an open research laboratory asking whether humans and AI agents can turn uncertain goals into trustworthy software by separating generation from acceptance. Its first installable tool, idkmesh gate-audit, measures what a review panel is actually worth: effective independent votes rather than head-count, error-correlation structure, and the breach rate of seeded known-bad candidates.

1.00 effective votes of 251.66× heuristic overstates3.7× error cut
  • E017 measured 25 independently seeded test oracles — programs, over a 72-candidate corpus with ground truth from executing hidden tests — at an effective panel size of 1.00
  • The standard N/(1+(N−1)ρ) heuristic predicted 1.66, so it overstates exactly where it is relied on
  • Changing the aggregation rule cut error 3.7×; growing the panel bought nothing
  • E016 is retained as a negative result: 20 live LLM verifiers did not verify, so no AI review panel has been measured here
  • Negative results and failed experiments are kept, not hidden — evidence must survive independent scrutiny
PythonLLM EvalVerificationGitHub Actions
GRAAFE code ↗

Graph anomaly-anticipation for exascale HPC — topology-aware node-failure prediction running in production on CINECA's Tier-0 Marconi100, published in FGCS.

FGCS 2024Graph modelTier-0 deployment
  • Models the machine as a graph and predicts, per node, the probability of an anomaly in a future window
  • Benchmarked by AUC against per-node DNN, gradient-boosting, random-forest and decision-tree baselines
  • Trained offline, then served online as a Kubeflow pipeline reading live ExaMon telemetry over MQTT
  • The paper reports negligible added overhead versus running the monitoring system alone
PythonGCNPrometheusHPC
HazardNet code ↗

Thermal-hazard prediction for datacenters — multi-modal deep learning forecasting thermal failures fast enough to act, with explanations operators trust.

3,312 nodes6 h horizonFGCS 2024
  • A year of inlet/outlet temperature and power telemetry from 3,312 nodes of CINECA's Marconi A2
  • Temporal Convolutional Network, LSTM and SVM models over a rolling time window
  • Six-hour prediction horizon — chosen with the facility manager, not with a grid search
  • Training data published openly on Zenodo so the result can be reproduced
PythonPyTorchTCNLSTM
ExaMLOps SEANERGYS · architect & lead dev code ↗

An end-to-end MLOps platform for HPC workload management, built for the EuroHPC SEANERGYS project and now running in production on European HPC infrastructure. Architect, lead designer and main developer; WP3 task lead at Bologna. It is model-agnostic and multi-tenant — any of the sixteen consortium partners registers a model and the platform auto-discovers and operationalises it (train → version → govern → serve → monitor) without ever owning the model code. The whole loop, on a real supercomputer, behind an operator approval gate.

  • Auto-discovery training pipelines in Prefect: every registered model × dataset pair runs train → evaluate → log → promote
  • Slurm adapter for HPC job orchestration; a DataPlane bridge carries messages off the machine
  • MLflow registry with a multi-stage lifecycle and a YAML model registry with per-environment overlays
  • Ray Serve multi-model serving with batched inference; MinIO for artifacts
  • A sysadmin approval gate stands between a promoted model and the serving fleet — nothing goes live unattended
  • Prometheus, Grafana and Loki for metrics and logs; React 19 + FastAPI dashboard; exa operator CLI
MODELMODELMODEL TRAINprefect REGISTRYmlflow stages APPROVEsysadmin gate SERVEray serve
any partner's model — one governed path
PythonPrefectMLflowRay ServeSlurmMinIOFastAPIReact 19Kubernetes
kube_q code ↗

The operator's companion for KubeIntellect — a CLI and Python SDK (kq) exposing the full agent API with streaming output and a human-approval UX, built for CI/CD.

  • Full KubeIntellect API coverage from the terminal
  • Streaming Rich TUI · pipeline-friendly output
PythonRichCLISDK

// ships  —  open-source systems

Research is half of it. I also ship.

Privacy-first, local-first tools — built to be installed and used, not just cited.

NovaFabric agent replay & evidence · beta details → code ↗ live ↗

NovaFabric is open-source, self-hosted replay and evidence infrastructure for AI agents and agentic systems. It captures agent executions as portable Run Capsules for replay, behavioral/structural diff, lineage, cryptographic provenance, assurance and audit — with no application-code changes. It also supports local, Docker, Kubernetes and SLURM/HPC execution environments.

  • Zero-code-change capture · four explicit replay modes (exact / mocked / semantic / forensic)
  • Cryptographic seal: DSSE signature + RFC 3161 timestamp + append-only Merkle log
  • Structured run-to-run diff as a CI regression gate; signed evidence bundles verify without it installed
  • Runs offline from a laptop to an HPC cluster — no cloud, no account
  • Apache-2.0 · beta / pre-v1 · core local workflows are self-hosted and offline-first
CAPTUREno code changes SEALsigned REPLAY4 modes DIFFCI gate AUDITstandalone
one run in → a signed capsule that still verifies years later
PythonGoOpenTelemetry GenAISigstoreOPA/RegoApache-2.0
YazSes formerly NovaVoice shipping · v2.17.0 overview → docs ↗ code ↗

Hold a key, speak, release — fully on-device voice dictation that types into any app and runs voice commands. No cloud, no subscription, no data leaving your machine. Shipped and maintained across multiple releases.

  • On-device faster-whisper (CPU int8) — no GPU, no network, no account
  • Also transcribes recordings and captures whole meetings with speaker labels
  • Editor/terminal voice commands; Neovim LSP context; accessibility-first design
  • Linux · macOS · Windows — APT, Snap, pipx/PyPI
  • 23 releases on PyPI · 401 commits · 10 contributors
THIS MACHINE NO CLOUD
hold → speak → release — the audio never leaves the machine
Pythonfaster-whisperllama.cppApache-2.0
vision2prod code ↗

A meta-framework for taking a vague idea to production without losing context, evidence, or decision rationale — for humans and AI agents alike.

4-stage pipeline657 tests
  • VisionForge → SOTAForge → DesignForge → BuildForge
  • Deterministic verification gates: schema, evidence, traceability — no LLM in the gate
  • v2p CLI + FastAPI/HTMX governance portal
PythonFastAPIHTMXpytest

// research

Peer-reviewed research in HPC, MLOps and AI operations.

18peer-reviewed
Google Scholar ↗ ORCID ↗
EU Horizon DECICE lead SEANERGYS lead Graph-Massivizer EUROPEAN PILOT REGALE EPI SGA1
  1. Journal of Grid Computing · 2026 · first author KubeIntellect: A Modular LLM-Orchestrated Agent Framework for End-to-End Kubernetes Management
  2. Scientific Data (Nature Portfolio) · 2023 M100 ExaData: A Data Collection Campaign on CINECA's Marconi100 Tier-0 Supercomputer
  3. SC'23 Workshops (ACM) · 2023 PM100: A Job Power Consumption Dataset of a Large-Scale Production HPC System
  4. Future Generation Computer Systems · 2024 GRAAFE: GRaph Anomaly Anticipation Framework for Exascale HPC Systems
  5. Future Generation Computer Systems · 2026 · first author Elevating Datacenter Resilience with ThermADNet: A Thermal Anomaly Detection System
  6. DATE · 2021 · first author Prediction of Thermal Hazards in a Real Datacenter Room Using Temporal Convolutional Networks

All 17 publications, with DOIs and BibTeX →

Program committee

PDP 2025 · PDP 2026 · AsHES 2026

Reviewer

IEEE TCAD · FGCS · J. Grid Computing · SC · ACM CF · DATE · PDP · AsHES

Supervision

2 PhD co-advisees · 5 MSc theses · Lab of Big Data Architectures, UniBo

// stack

The toolchain behind the work.

Agentic AI / ML

PythonPyTorchLangGraphLangChain MCPA2AAnthropic SDKFastAPI

MLOps & serving

PrefectMLflowRay ServeMinIO KubeflowGitHub ActionsGitLab CI

Cloud-native & infra

KubernetesHelmTerraformDocker Azure AKSNGINXLinux

Observability

PrometheusGrafanaLokiTempo OpenTelemetryAlertmanager

HPC

SLURMMPIOpenMPApptainerExaMon

Foundations

NetworkingVMwareActive Directory SDNBashGit

// hire me

Hire a freelance AI platform, agentic AI, MLOps and Kubernetes engineer.

Fixed-price starter audits to begin low-risk, or project work at a senior day rate. Based in Italy, I work remotely across Europe and internationally (Europe/Rome time zone). I build systems your team can maintain after I'm gone — not black boxes.

Kubernetes reliability & AIOps

Health-checks, observability, hardening, incident root-cause, and ops automation with human-approval gates.

Health-Check & Triage — €250Postmortem — €150Projects €400/day

MLOps & ML in production

Get models out of the notebook: registry, serving, drift detection, governed retraining, monitoring — the stack I run in production on EuroHPC.

Readiness Audit — €300Serving/Drift Review — €200Projects €400/day

Production LLM agents

Agents that act on real systems — tool-use, human-in-the-loop safety, tracing, and an audit trail you can defend.

Architecture Review — €200Observability & Audit — €250Projects €400/day

Full details, how an engagement runs, and the questions people usually ask → mskazemi.com/hire. Free 30-minute scoping call → mohsen.seyedkazemi@gmail.com.

// questions

Questions people ask.

Who is Mohsen Seyedkazemi Ardebili?

Mohsen Seyedkazemi Ardebili is an AI Platform & Agentic Systems Engineer and independent consultant. He builds AI platform, MLOps and agentic systems across Kubernetes, OpenShift and HPC, including KubeIntellect for human-governed Kubernetes operations and NovaFabric for replayable, verifiable execution evidence for AI agents.

What is an AI SRE, and how is it different from a chatbot for Kubernetes?

An AI SRE investigates and acts on a live cluster, where a chatbot only explains. It gathers its own evidence from real tools — kubectl, Prometheus, Loki — reasons about what is actually failing, and then executes the fix. The difference that matters in production is the approval gate: a human authorises the change, and the whole chain is left as an audit trail.

Is Mohsen available for full-time, contract or freelance work?

Yes — open to relevant full-time roles, contracts and freelance projects; based in Italy and working remotely across Europe and internationally. Engagements run in three areas: Kubernetes reliability and AIOps, MLOps and machine learning in production, and production LLM agents. Each one can start with a fixed-price audit, so you can see the work before committing to a project. Details are on the hire page.

What kind of infrastructure problems does he work on?

Kubernetes incident root-cause analysis, observability and hardening; model registries, serving, drift detection and governed retraining; and the safety layer around LLM agents — tool boundaries, scoped RBAC, human-in-the-loop gates, tracing and audit trails. The research half is anomaly detection and prediction on Tier-0 HPC clusters.

What is the background behind the research?

Nearly nine years in enterprise IT and network operations, six of them as the IT and network administrator of a combined-cycle power plant of more than 1,000 MW — an environment with no staging and no undo — followed by a PhD at the University of Bologna on detecting and predicting thermal anomalies in a Tier-0 supercomputer. Operations first, research second, which is why the systems ask before they act.

// contact

Let's build infrastructure that runs itself.

Open to research collaborations, open-source work, and industry partnerships in AI infrastructure, HPC, and autonomous operations.